How many users will visit your website next week? How do you suggest items to customers that they actually want to buy? Which version of this paragraph you’re reading right now will cause you to stay on the page longer? How many Taylor Swift songs in one Release Radar playlist is too many? These are the kinds of questions that you can answer with data science. It’s an umbrella term, and there’s a lot of industry jargon, but data science can be broadly defined as the process of extracting meaningful insights from data.
In simple terms, this process includes:
Deciding what questions you can (and should) ask of your data
Obtaining and processing data into a usable format
The actual answering of questions or extracting insights from the data— or building predictive models to forecast future data or simulate scenarios
And crucially: the presentation and communication of these insights to others, so that action can be taken.
From extracting insights from unstructured data to creating predictive models using machine learning, data science is an incredibly important function, with the potential to have major business impact if done right. It is also a complex field to master, with many complex subtopics and specializations to understand. This page provides interactive and explanatory examples of some of the most common data science use cases and subtopics. If you see something interesting, click “Get a copy” to start exploring and customizing any example for yourself.
See what else Hex can do
Discover how other data scientists and analysts use Hex for everything from dashboards to deep dives.
While both data science and data analytics involve working with data, they differ in scope and approach. Data analytics primarily focuses on analyzing historical data to provide insights on what has happened. Data science, on the other hand, uses complex algorithms and predictive models to understand what might happen in the future.
Python's popularity in data science is due to its simplicity and wide range of libraries and frameworks like Pandas, NumPy, and Matplotlib, which simplify tasks such as data cleaning, analysis, visualization, and predictive modeling.
Core skills include a good grasp of mathematics and statistics, programming skills (primarily in Python or R), knowledge of machine learning algorithms, and data wrangling and analysis. Also crucial are visualization skills, domain knowledge, and the ability to communicate complex results clearly.
Data can be structured (organized in a defined manner like SQL databases), unstructured (not organized in a pre-defined manner, such as text, images, and social media posts), or semi-structured (a mix of the two, like JSON files).
Big data refers to extremely large datasets that are often too complex to be dealt with by traditional data-processing software. Data science techniques are employed to extract meaningful insights from these big data sets.
Data cleaning is the process of detecting and correcting or removing corrupt, inaccurate, or irrelevant parts of data. As the quality of data significantly affects the outcome of data analysis, data cleaning is a critical step in the data science process.
A predictive model is a mathematical tool that uses historical data to predict future outcomes. It identifies patterns in the data and applies these patterns to forecast future events.
Data visualization involves presenting data in a visual context, such as charts or graphs, to help stakeholders understand complex patterns within the data. It aids in making data-driven decisions by allowing clear and quick interpretation of data and its trends.
Challenges include dealing with messy and large datasets, ensuring data privacy and security, communicating complex results to non-technical audiences, and staying updated with the latest tools and techniques in the rapidly evolving field of data science.
The key steps include identifying the problem or question, collecting and cleaning the data, exploring and analyzing the data, building and evaluating models or hypotheses, and finally, presenting and communicating the findings.
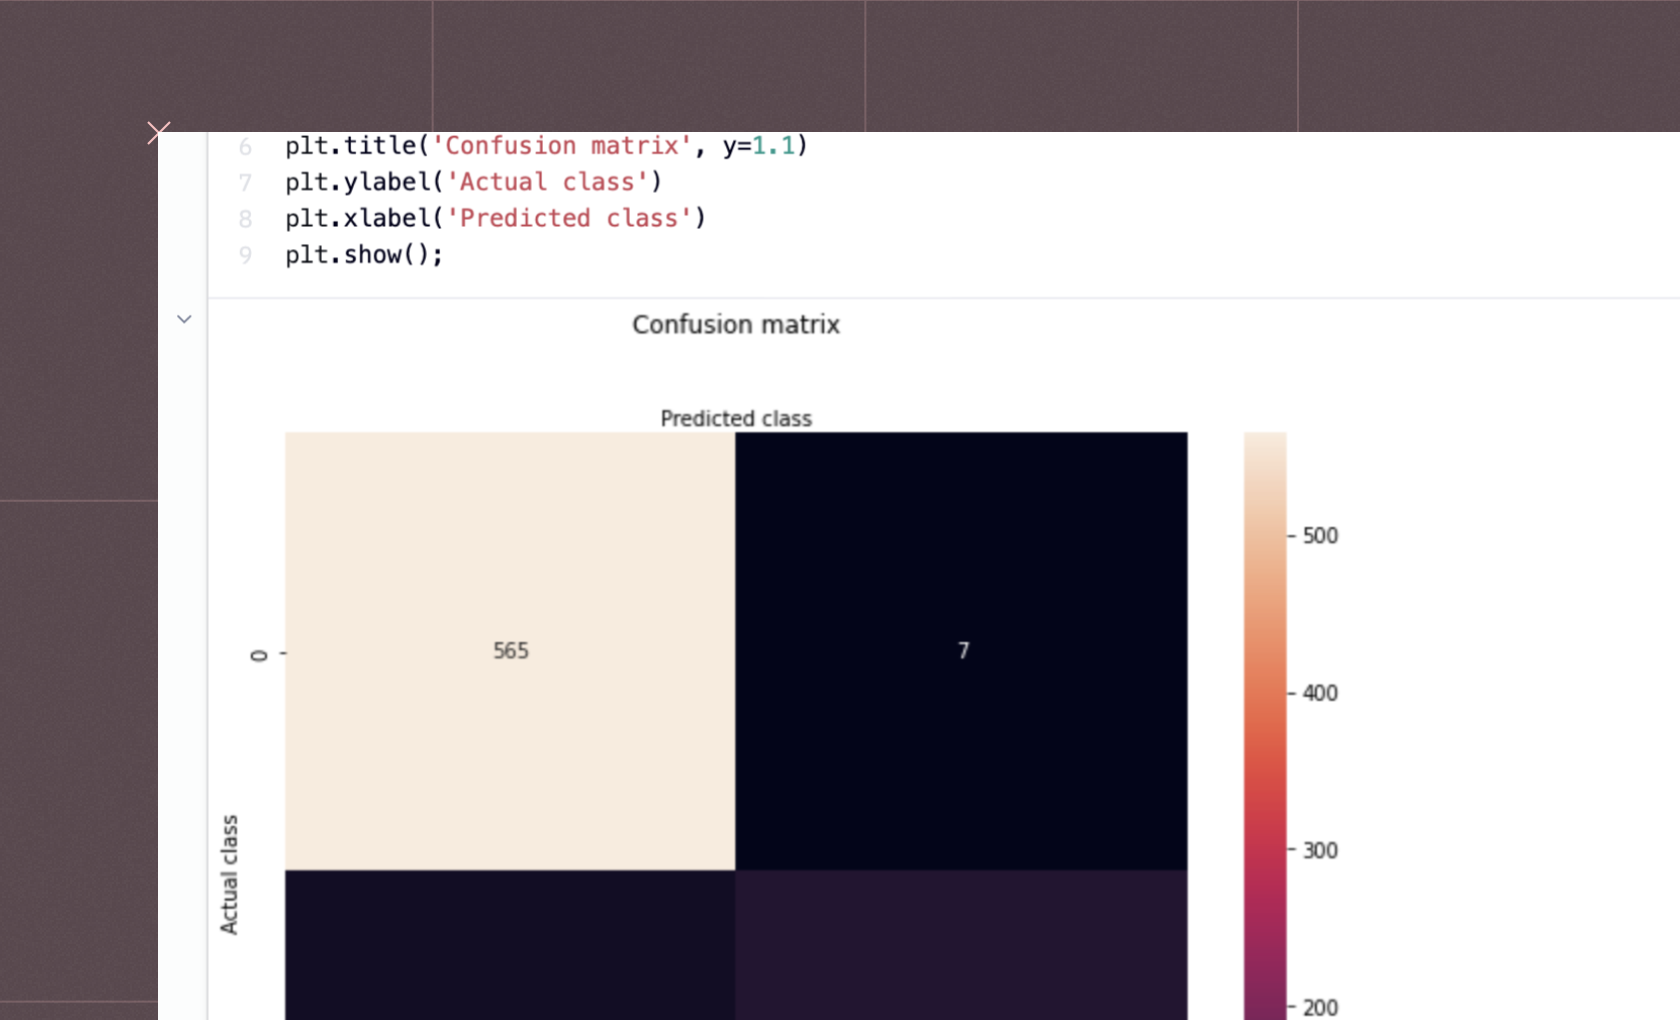
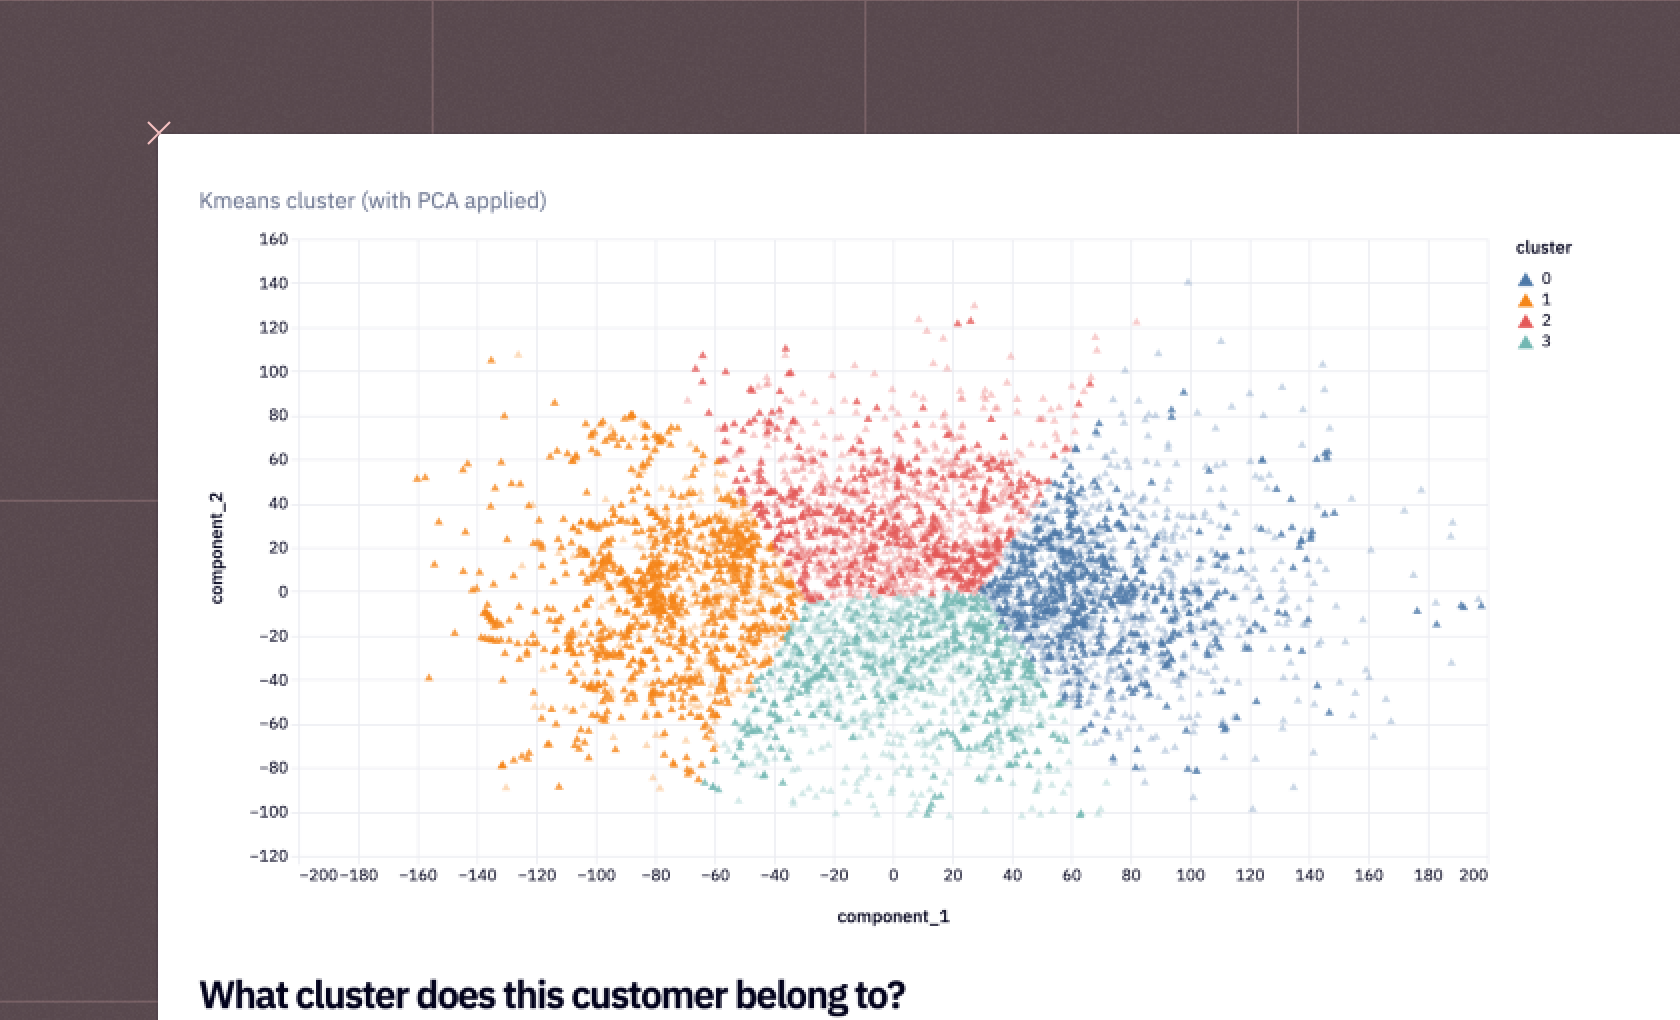
Machine learning is a key component of data science that involves creating and using algorithms to make predictions or decisions without being explicitly programmed to do so. Applications include recommendation systems, image recognition, and natural language processing. These algorithms learn from data and improve their performance over time, enabling data scientists to generate insights, forecast trends, and create data-driven solutions.
Learning data science involves acquiring skills in mathematics, statistics, programming (particularly in Python or R), and machine learning. You can learn these through online courses, textbooks, tutorials, or degree programs. Working on practical projects and problems, and understanding domain knowledge is also vital for applying data science concepts effectively.
NLP, or Natural Language Processing, is a subfield of data science that focuses on the interaction between computers and human language. It involves teaching machines to understand, interpret, generate, and manipulate human language, enabling applications such as language translation, sentiment analysis, speech recognition, and chatbots.
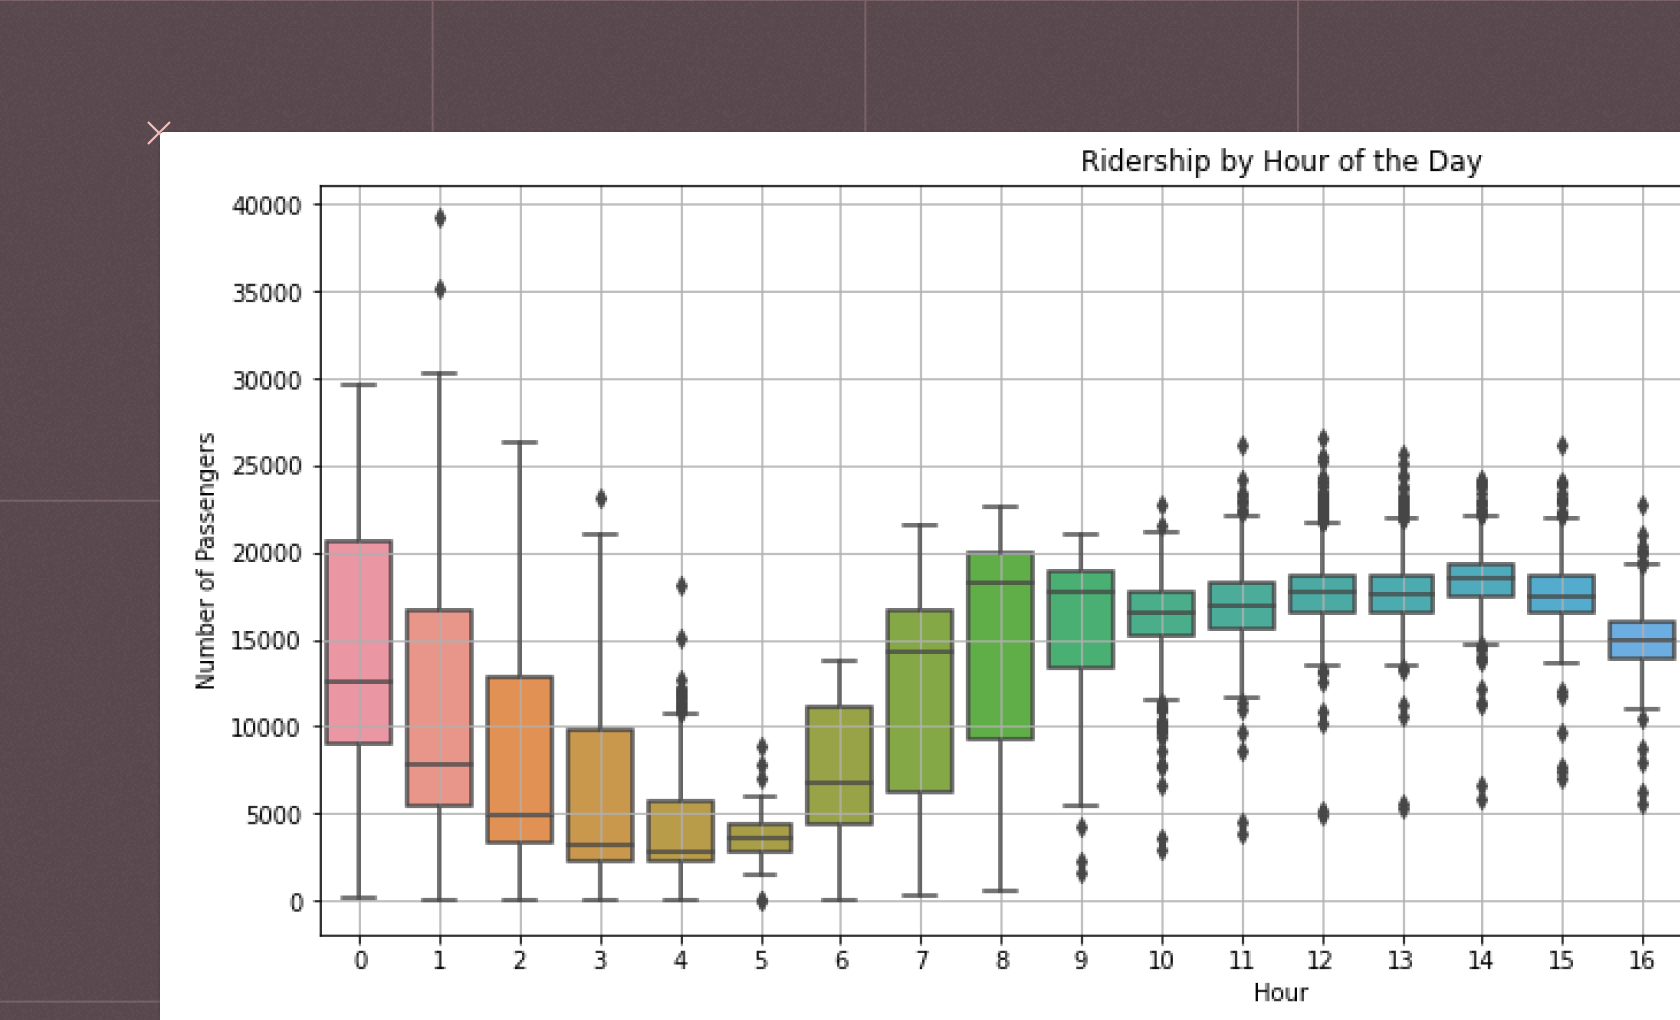
EDA, or Exploratory Data Analysis, is an approach in data science where one analyzes datasets to summarize their main characteristics, often using statistical graphics and other data visualization methods. It helps to understand the data, identify patterns, spot anomalies, test hypotheses, and check assumptions.
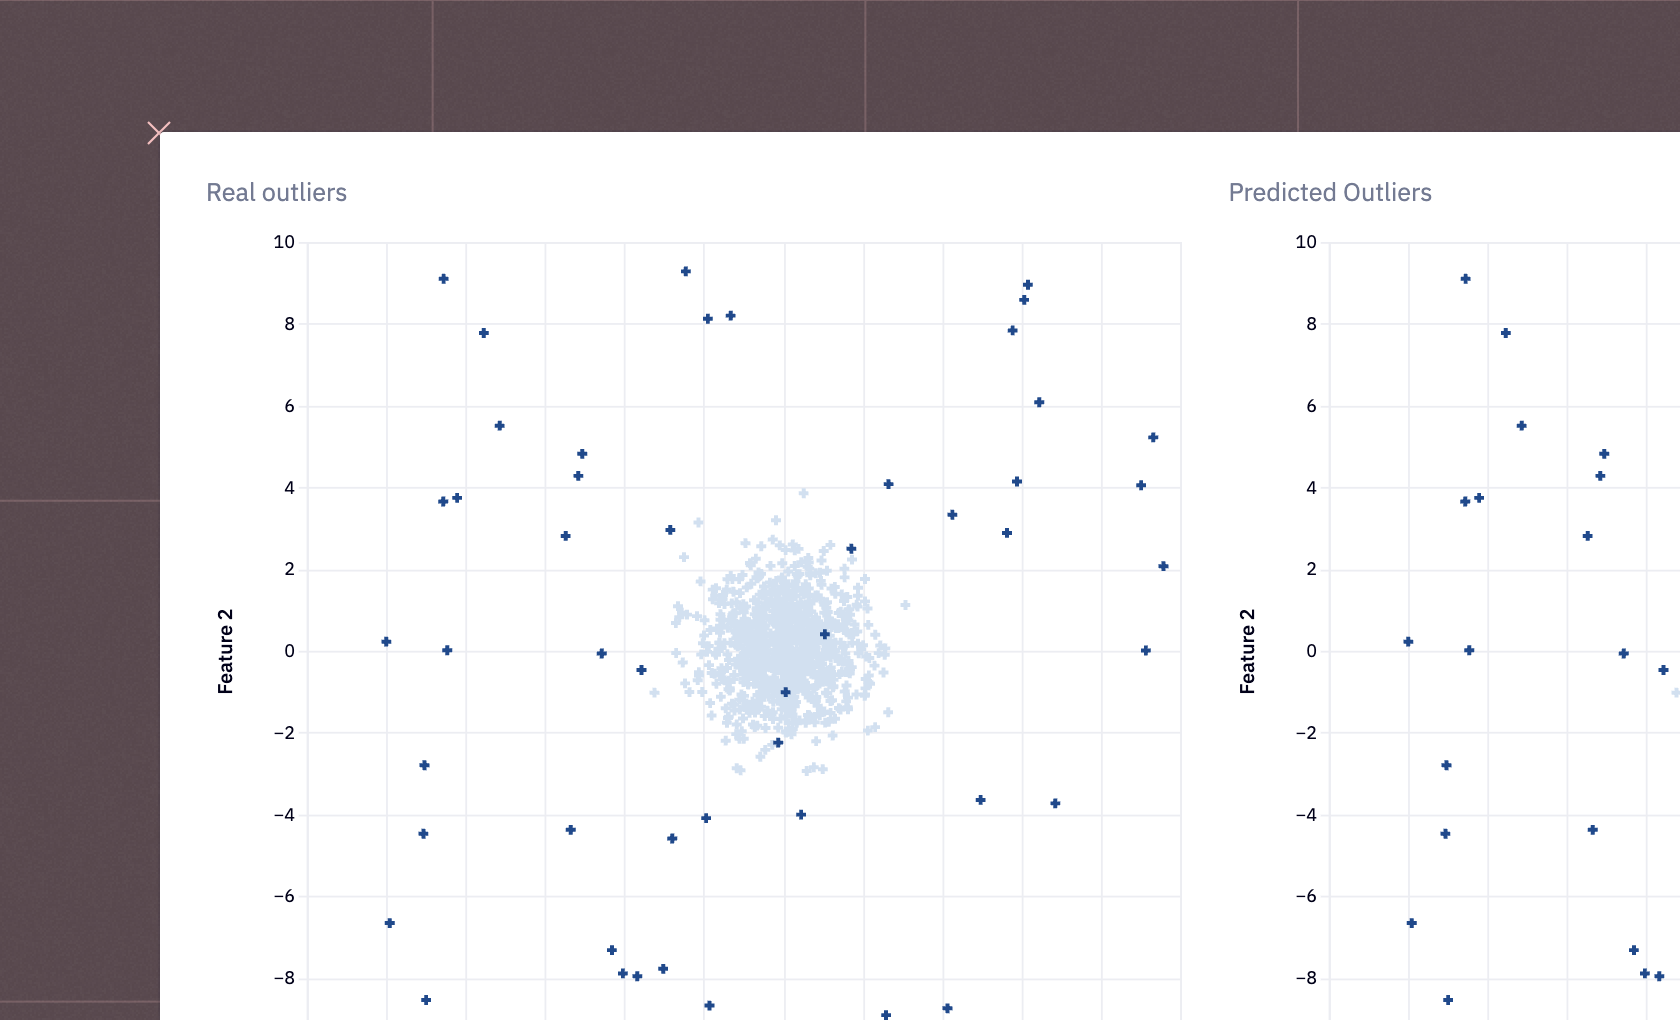
Feature engineering is the process of transforming raw data into features, or input variables, that better represent the underlying patterns in the data, thereby improving the performance of machine learning models. It involves steps like handling missing data, dealing with outliers, and creating interaction features to capture complex relationships.
Learning Python for data science involves understanding Python's basic syntax and control structures, and then learning to use key libraries like Pandas for data manipulation, NumPy for numerical computations, Matplotlib for visualization, and Scikit-learn for machine learning. Various online courses, books, tutorials, and hands-on projects are available to help you master Python for data science.